Testing 12 language models side by side
Independent evaluation · Copenhagen · 2024
Every month a new AI model claims to be the best. Companies asking me which one to use deserved a better answer than a benchmark from the model’s own maker. So I tested them myself, on the work my clients actually do.
In numbers
- Time: one automated run tests every model in about 6 hours, work that would take around 3 weeks by hand. The fastest local model wrote 45 tokens a second.
- Money: per thousand answers, about €12 for the largest cloud model and €0.4 for a small one. A local model costs €0 per request.
- Errors: on one narrow task, a small local model scored 91% against 95% for the best cloud model. On general questions, small models invented facts in 9% of answers, the best in 3%.
- Adoption: the results shaped 2 projects, BikeNorth and Aule Writer, and went to 4 companies choosing a model.
- Scale: 12 models, 3 tasks and 40 prompts per task: 1,440 answers scored.
The models
ChatGPT, Google Gemini, Grok, Kimi, Qwen, Llama, Mistral and Phi, among others: 12 in total. The cloud models through their APIs, and the open ones on my own machine with Docker and Ollama.
The method
- The same 40 prompts for every model, per task: summarising reports, rewriting text for customers, and answering questions from general knowledge.
- A checklist per answer: is it correct, complete and in the right tone, and does it invent anything?
- Speed and cost: tokens per second on the same hardware for local models, and the price per thousand answers for the cloud ones.
- Bias and fairness: the same question about different groups of people, compared side by side.
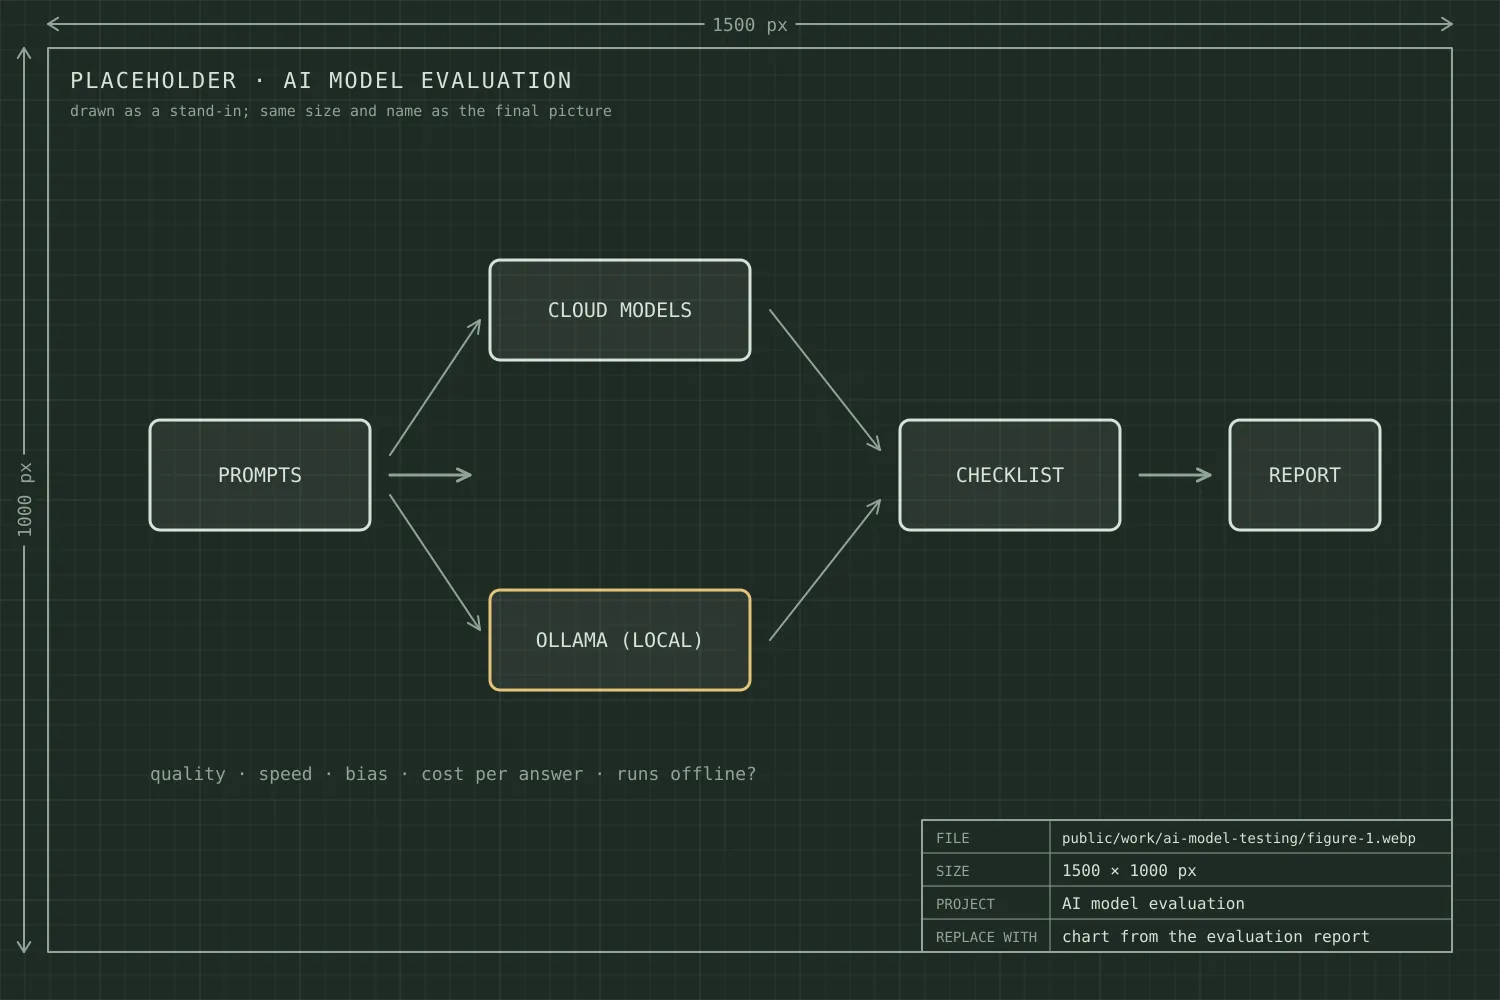
One pipeline for every model, cloud or local.
What I found
The biggest cloud models were the best all-rounders. But for one narrow, repeated task, a small model running locally came within a few points of them: fast enough, free per request, and with no data leaving the building.
That finding shaped my next two projects. BikeNorth now reads its booking emails with a small model fine-tuned for that one job, and Aule Writer keeps students’ writing on the school’s own machines.